A neural network uses the same learned weights for many predictions. Keeping those weights in a resistive memory array lets an electrical circuit calculate weighted sums where the values are stored. How much work does this save once inputs, conversions and intermediate results are counted?
Four experimental studies provide different parts of the answer. A phase-change memory chip shows how read precision changes throughput. A resistive switching chip demonstrates image classification and identifies the data transfers omitted from its peak efficiency figure. Two studies published in 2026 examine the cost of programming weights and the difficulty of fitting a small vision model to a physical array. Together they explain where a fixed model could benefit, which measurements can be compared and what a system designer would still need to know before estimating energy per prediction or the cost of deployment.
Which journey disappears?
Consider an image classifier that uses the same learned filter on patch after patch. A digital processor reads the filter from registers or buffers. A resistive array can leave the filter in its cells and use their conductance to calculate a weighted sum as each new patch arrives. View a diagram of the two data paths.
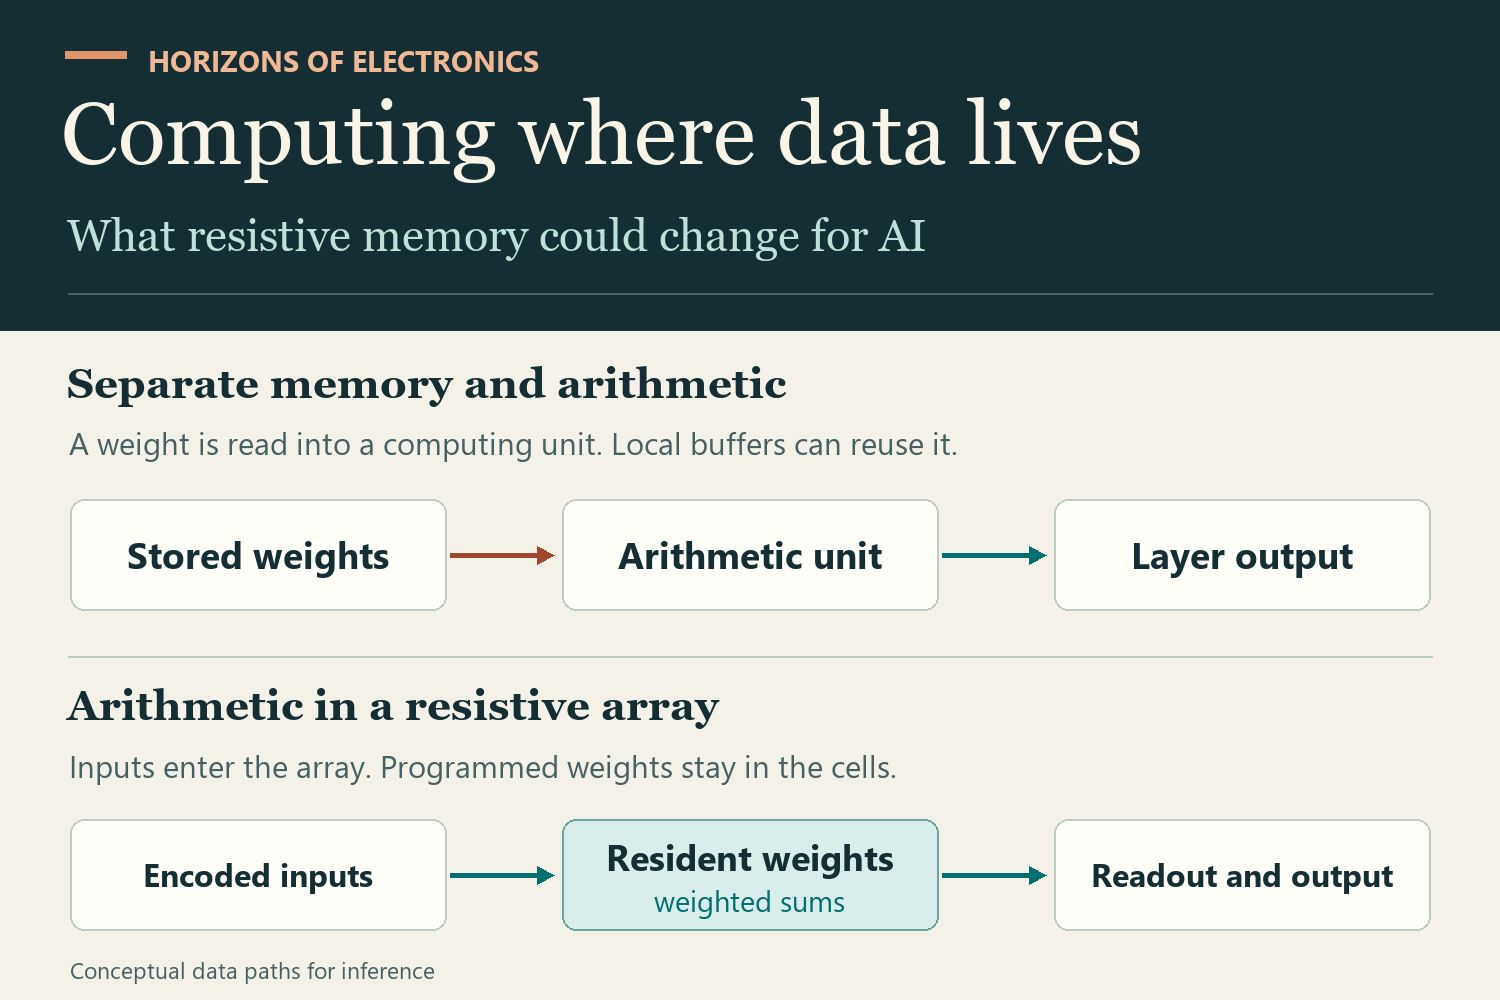
Consider a column of cells in an idealised array. A cell’s conductance encodes a weight. Applying an input voltage produces a current proportional to their product. Currents from several cells can add along a wire, giving a physical representation of a dot product. Practical chips differ in how they encode inputs, represent negative weights and sense the result. The stored weight participates directly in the operation. The input still has to reach the array, and the output has to be read and passed to the next stage. [1] [2]
A memristive cell stores information in its conductance: a programming pulse changes how readily the cell conducts when it is read later. A weight can use more than one cell, for instance to represent its sign. Two technologies illustrate the idea. Phase-change memory (PCM) uses a material whose electrical conductance depends on its physical phase. The resistive random-access memory (RRAM) in NeuRRAM uses an oxide switching layer. Both can retain programmed values between predictions. Their programming behaviour, variability and read circuits differ. In PCM, conductance can drift with time. In NeuRRAM, the researchers characterised conductance relaxation and used repeated writes and checks to reach target values. Those effects influence the precision an application can maintain. [1] [2]
What fabricated chips establish
Read precision changes the answer on the same chip
IBM’s 64-core PCM chip connects analogue arrays to digital processing and on-chip communication. With 8-bit inputs and outputs, its peak matrix–vector throughput was 63.1 trillion operations per second in single-phase read mode and 16.1 trillion in the more precise four-phase mode. Corresponding peak efficiencies were 9.76 and 2.48 trillion operations per joule. The study counts a multiply and an addition as two operations. [1]
The accuracy tests used the four-phase mode. On CIFAR-10, a custom ResNet-9 reached 92.81% accuracy with the two-device programming strategy, compared with 93.67% in its software reference. Quoting that accuracy alongside the single-phase peak would combine two operating conditions. Although both studies used CIFAR-10, this ResNet-9 and the ResNet-20 below are different networks. Their accuracies cannot rank the two memory technologies. [1]
Accuracy and energy can have different measurement boundaries
In the CIFAR-10 test, the 48-core NeuRRAM chip performed the convolutions of a ResNet-20 classifier. A separate programmable circuit on the same board accumulated partial sums and computed average pooling. Accuracy rose from 83.67% to 85.7% after the network was fine-tuned using chip measurements; the software model with four-bit weights reached 87.03%. Their efficiency tests answer a narrower question. The peak figures assume full array utilisation and exclude the time and energy needed to buffer and move intermediate results. The task accuracy therefore supplies one part of an application comparison. Energy per completed image still requires a measurement that includes those transfers. [2]
The cost of writing the weights can change the design
A 2026 study used a 40 nm resistive chip with randomly initialised weights. Its training procedure selected connections to retain or switch off, reducing the need to tune individual cells to precise targets. On Fashion-MNIST the hardware-assisted pruning method achieved 87.4% classification accuracy. For one image, the authors estimated about 3.67 microjoules for their hybrid design at 40 nm and 5.76 for their GPU reference. They then projected the hybrid design to 5 nm, obtaining 1.25 microjoules. The reported 78.3% saving uses that projected value; the researchers did not measure it on a 5 nm chip. The authors also studied a larger network by simulation. Each result identifies a different stage between a device experiment and deployment. [3]
A small vision model asks a different question of the array
A second 2026 study examined a filter that acts separately on each image channel. Such a layer can leave much of a conventional dense array idle. The team fabricated a chip with selection lines arranged to use more of the array for these filters. A tailored MobileNetV1Small classified whether a person was present in an image from the Visual Wake Words task, with 80.36% measured accuracy. The first layer, final pooling and classifier used digital processing. The paper’s 21.3 trillion operations per joule at 100 MHz describes a neural processing core. An energy figure for a complete camera decision would also need the remaining stages and the chosen sensor boundary. [4]
What would change for an AI application?
| Question | What to compare |
|---|---|
| How much data moves? | Count weight, activation and intermediate-result bytes across the same physical interface. Record which weights fit locally in each design and how often they are reused. |
| How quickly does it respond? | Time the same input through to the same output, at a declared batch size. Include conversion, buffering, digital work and, where relevant, wake-up. |
| What energy buys one prediction? | Measure energy at the same power boundary and quality target. Record idle power, weight programming and verification, recalibration and the number of predictions over which they are spread. |
| What capacity and cost follow? | Check how much of the useful model fits, which layers keep the arrays busy and how much work spills elsewhere. Device cost, lifetime, utilisation and replacement frequency enter a deployment estimate. |
A fixed filter running repeatedly beside a sensor presents a different opportunity from a service that frequently swaps models. In the first case, many predictions can share the initial programming cost. In the second, weight changes and their verification may occupy a substantial part of the available time. A fair experiment would run both implementations over the same sequence of requests, record their accuracy as the device ages and meter the complete workload over that interval.
The experiments show that resistive arrays can perform useful neural-network operations and support working classifiers. The size of the system benefit remains a property of the workload, its mapping and the comparison machine. The selected studies supply neither a common end-to-end energy saving at matched quality nor a price per inference. Those are measurable questions for a particular deployment.
Sources and scope
This selective review covers evidence examined through 14 November 2026. The cited measurements come from the device teams. This selection does not establish whether other groups have independently reproduced them. The evidence includes chip measurements, model accuracy results and explicitly labelled estimates. The review includes no new hardware measurements.
- A 64-core mixed-signal in-memory compute chip based on phase-change memory for deep neural network inference. Nature Electronics (2023). Figure 3 and the chip performance table. Authors’ publication record.
- A compute-in-memory chip based on resistive random-access memory. Nature (2022). Figures 1 and 5; Methods, including the CIFAR-10 implementation and energy measurements. Open full text.
- Pruning random resistive memory for optimizing analog AI. Nature Communications (2026). Figure 3d–g distinguishes hardware classification from energy estimates.
- A Memristor-Based In-Memory Computing System-on-Chip with Efficient Depthwise Convolution. Advanced Intelligent Systems (2026). Table 1 and Figure 4 locate the digital stages and identify the evaluation task.
Liked this post? Follow this blog to get more.